Inside the AI data centre · Compute hall
The Compute Rack
This section explores NVIDIA Vera Rubin NVL72, the newest AI rack platform NVIDIA provides: a whole rack of Rubin GPUs and Vera CPUs, liquid-cooled and joined so tightly that it works as one machine.
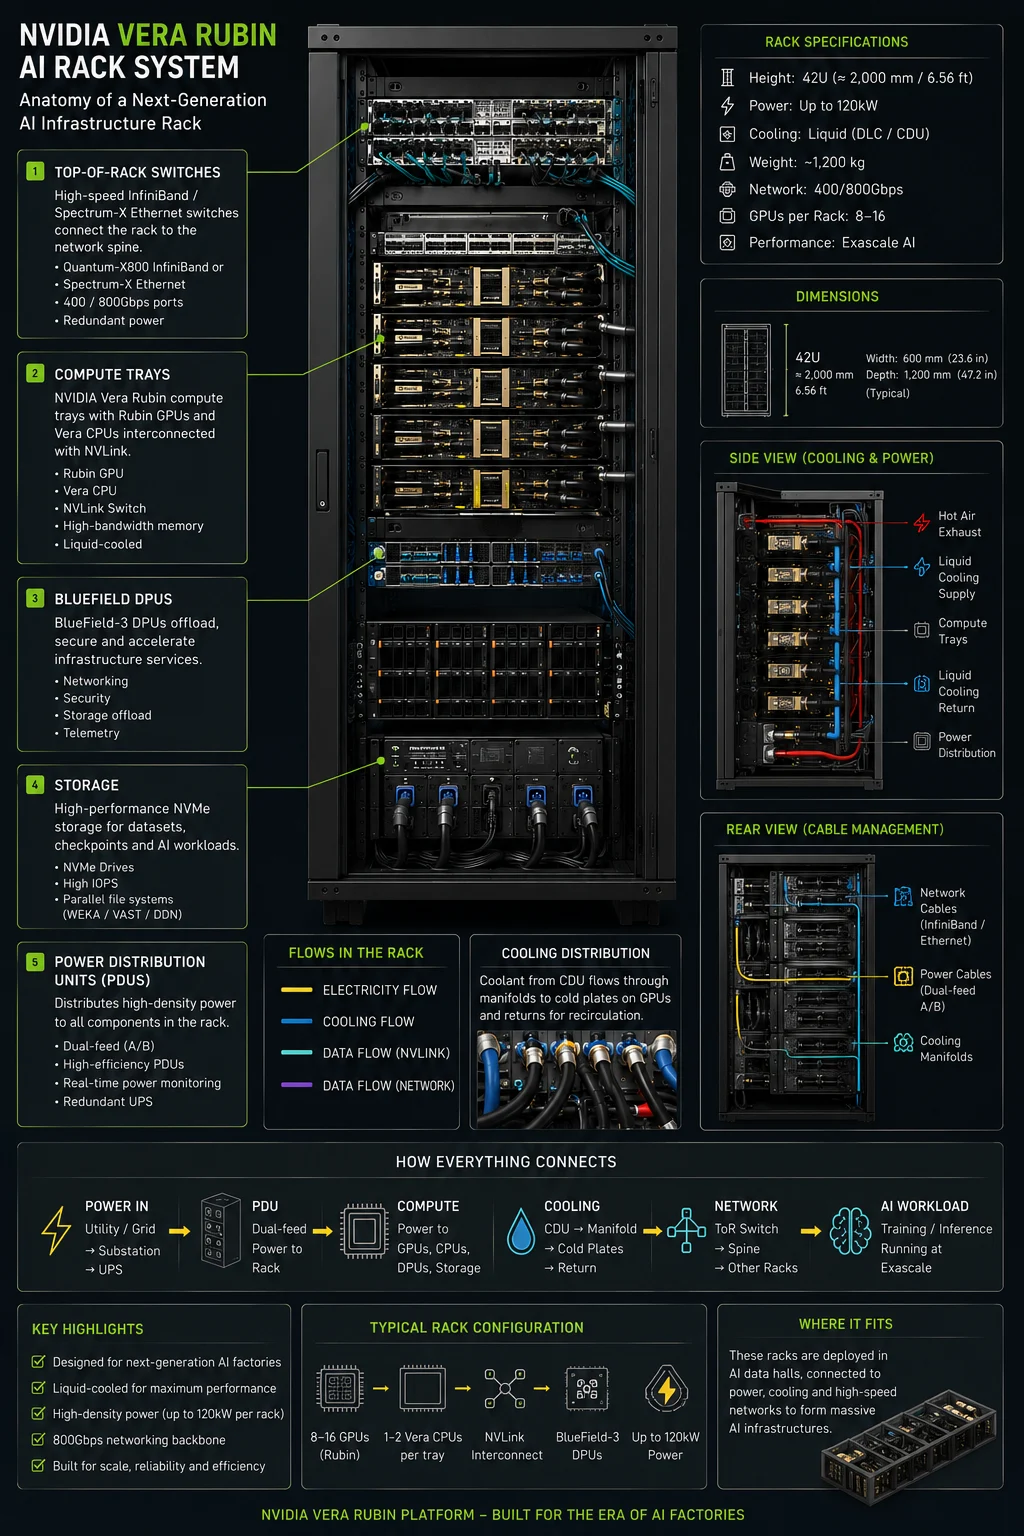
Illustrative model — author-supplied, not official vendor material. The drawing is a generic GPU rack, not the Vera Rubin NVL72 layout. NVIDIA's published rack holds 18 compute trays (72 Rubin GPUs, 36 Vera CPUs) and 9 NVLink switch trays, and weighs ~4,000 lb (≈1,800 kg). Its in-rack switching is those NVLink switch trays; the scale-out leaf switches the drawing puts at the top typically sit in separate network racks. Open the ⓘ on the compute rack for the sourced specification.
Select a part to zoom in on it · 6 components · 10 diagram panels
Build sequence
How the rack is put together
Why is an AI rack delivered and accepted as one engineered system, not a cabinet to fill?
In the rack
Sources · 0/8 verified8 unsourced
The significant change across these generations is not accelerator performance but the unit of deployment moving from chip to server to rack to pod, which changes procurement, logistics, commissioning and failure-domain size together.
Industry reference patternReview required
No source attached. Working explanation, awaiting technical review.
Integrating and testing racks at a staging facility before shipping reduces on-site commissioning time and the number of faults discovered in the data hall.
Industry reference patternReview required
No source attached. Working explanation, awaiting technical review.
Vera Rubin is a coordinated platform spanning CPU, GPU, scale-up interconnect, scale-out networking, infrastructure processing, rack design, cooling, power and system software — not a single GPU product.
Vendor implementationReview required
No source attached. Working explanation, awaiting technical review.
Rack-scale AI systems commonly distribute power through shelves feeding a common busbar rather than individual per-server power supplies, which changes the rack-level failure domain.
Industry reference patternReview required
No source attached. Working explanation, awaiting technical review.
NVLink provides the high-bandwidth, low-latency interconnect within the scale-up domain, and NVLink switches extend that domain beyond a single tray.
Vendor implementationReview required
No source attached. Working explanation, awaiting technical review.
Liquid-cooled racks require leak detection, isolation valves and defined maintenance procedures, because a coolant leak is both an availability and an electrical-safety event.
Industry reference patternReview required
No source attached. Working explanation, awaiting technical review.
In a rail-optimised design each accelerator connects to a specific fabric plane, so collectives among the same-numbered accelerators across nodes stay within one rail and do not contend with the others.
Industry reference patternReview required
No source attached. Working explanation, awaiting technical review.
Out-of-band management must be reachable independently of the data fabric, or it is unavailable during precisely the incidents it exists to support.
Industry reference patternReview required
No source attached. Working explanation, awaiting technical review.
How everything connects
- View
- Physical
- Projection
- Compute rack
- Rev
- A
- Status
- Conceptual educational model
- Claims
- 14/152 verified
Note · This interactive model is a simplified educational representation. Exact component placement, capacity, power, cooling and network architecture vary by platform generation, deployment design and vendor configuration. Scale marker shows 2m — Reference value.